AI Sales Agent Evaluation Criteria for B2B Revenue Teams
Test whether it actually moves deals forward, not just checks feature boxes.
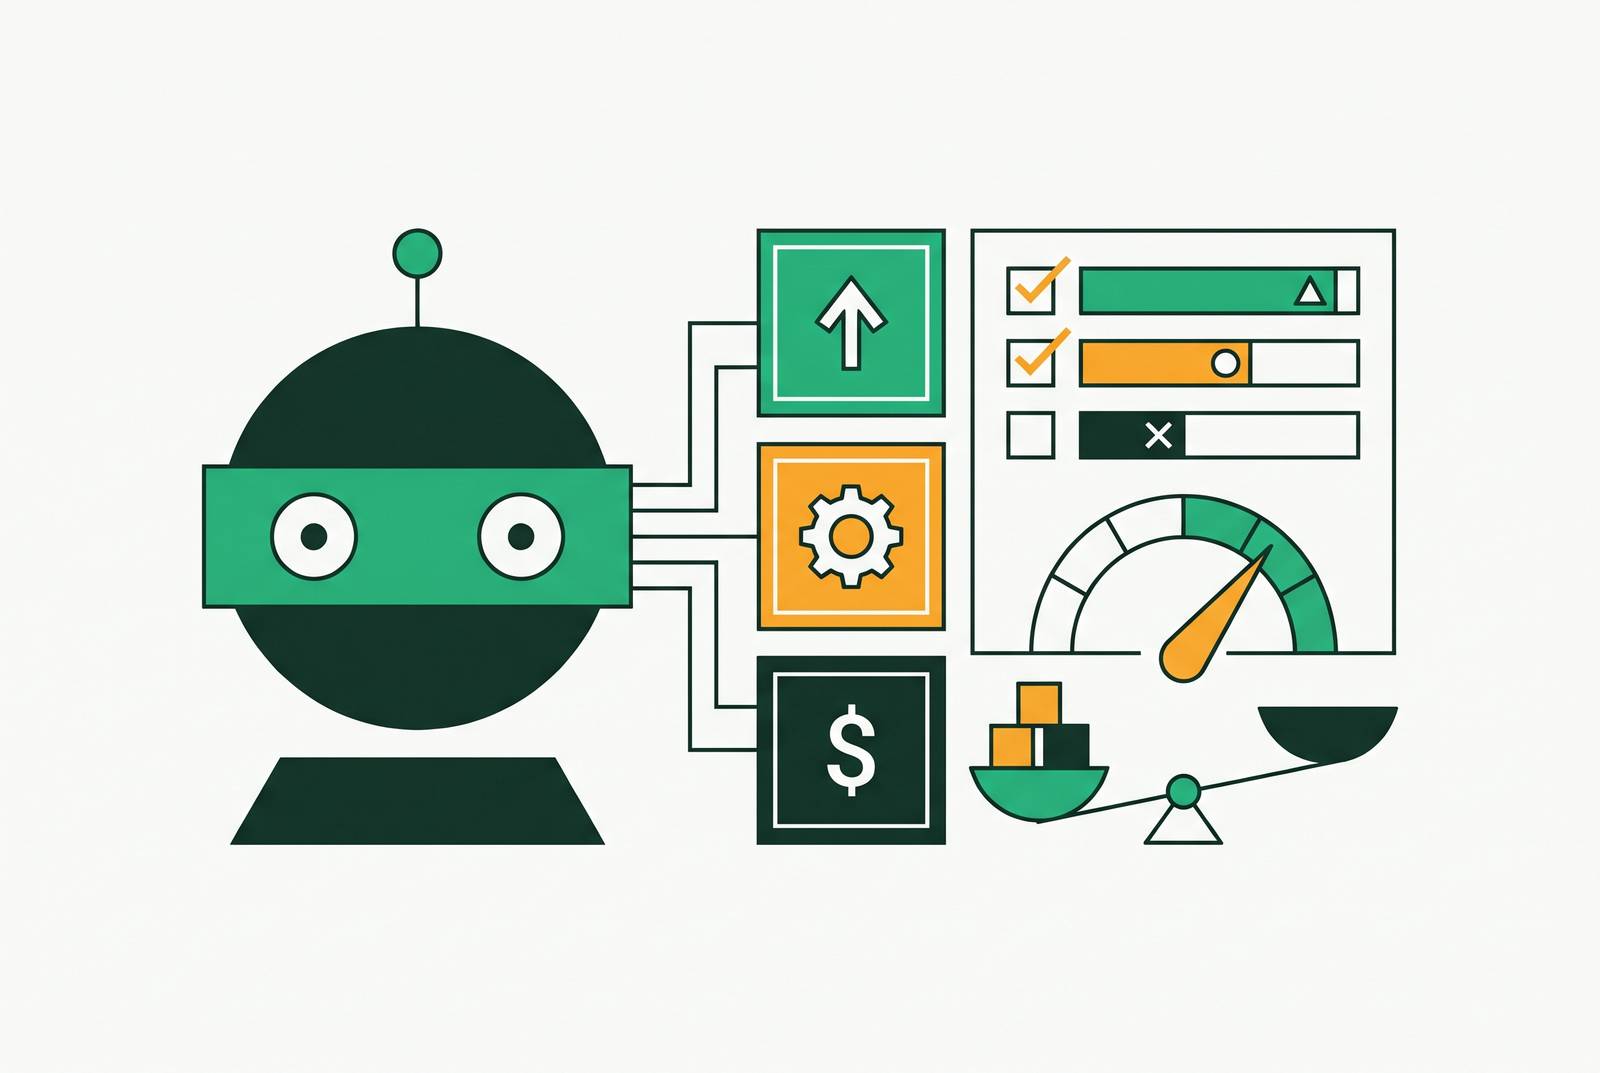
Choosing an AI sales agent for a B2B revenue team means testing whether it can turn live deal context into measurable pipeline progress. The right evaluation follows the work, from architecture and CRM updates through adaptation, data quality, human handoff, and revenue attribution. Feature counts are no substitute.
Why most AI sales agent deployments fail before they start
Teams select for feature count, send volume, or a polished demonstration rather than workflow fit, conversion quality, and attribution. A demo can make a tool look busy without showing whether its work helps a deal advance. Even a higher meeting-booking count from a fully autonomous setup need not produce more revenue than a hybrid human-plus-AI setup, because the closed-deal rate can reverse the volume advantage.
That selection error becomes expensive when the purchased tool solves a different problem from the one reps face. Mutiny's 2026 buyer framework points to an AI that gives the same generic suggestion no matter what the context is as a sign of this mistake. Reps need help with this deal. The evaluation therefore needs to distinguish workflow ownership, where a tool completes work end-to-end, from workflow assistance, where it helps a rep perform individual tasks. Both can be useful, but buying assistance when the job requires ownership is a route to shelfware.
How agentic architecture separates capable platforms from feature-decorated ones
Workflow ownership depends first on how the platform is built. A purpose-built agentic system can execute several connected steps, while AI layered onto a legacy platform may perform one task and stop at the next approval gate. Mutiny's framework contrasts multi-step execution in seconds, available in self-serve mode across GTM roles, with single-step features routed through legacy pipelines that depend on an admin or marketer. An AI button does not, by itself, make an agentic platform.
To test that distinction, ask the vendor to trigger a workflow spanning research, qualification, outreach, and a CRM update in one session. Watch the joins between tasks, not just the outputs. Specialized agents for research, qualification, enrichment, outreach, and scheduling should hand work to one another without someone having to restart the process. If every transition requires another tool or human intervention, the demonstration is showing assistance. Latency also helps tell them apart, because work done in seconds differs from a set of steps that takes hours.
Access is part of this architectural test too. Can a sales rep trigger and configure the workflow without an admin or marketing operations resource? A system may do a lot but still be limited to the roles its original platform was built for. The evaluator needs to see both connected execution and self-serve use by the people expected to run it.
What CRM integration actually means — and the real-time test that exposes shallow connectors
Architecture establishes what a platform can do in principle. CRM integration decides whether that work reaches the revenue team's system of record in time for the team to act on it. Check whether the tool reads and writes current data at the record level. A connector icon proves very little on its own. Mutiny's framework notes that tools that need nightly syncs act on data that is already hours old, so today's recommendation is based on yesterday's deal state.
Shallow integration also leaves work behind for people. With weak write-back, reps still have to do the CRM hygiene the agent was supposed to take off their hands, including recording enrichment, call summaries, and next steps. Custom automation middleware adds more work because someone has to keep that connection working as the CRM changes. Deep integration, by contrast, supports automatic field updates after agent actions and recommendations based on the current deal state. It also supplies the stage changes and closed-won status needed for attribution.
Ask the vendor's rep to perform a record-level action that updates the CRM in real time, during the demo. Mutiny's framework treats inability to show this as a failed real-time claim, regardless of the marketing page. A promised sync is not the same as a visible update. This test exposes the gap between a system that produces useful work and one that leaves a rep to ferry it home.
In-session adaptability — the criterion that separates AI with context from AI with templates
Current CRM data is necessary, but it does not guarantee a sensible response. The agent must also change its recommendation when something changes in the deal. That requires new context, such as a meeting outcome, reply sentiment, or objection, to reach the model during the session. Mutiny's framework describes why this is difficult for bolt-on AI when the base platform was not built to pass live context into the model.
Simulate a specific positive or negative meeting outcome and ask for the next recommended action immediately. Would the agent give the same advice if the meeting had gone the other way? If so, it fails this criterion, because it has not shown that the new information changed its reasoning.
The same test applies to replies and personalization. An objection, a buying signal, and a “not now” call for different responses. To respond to context, the agent also needs a tone that matches how the rep writes. That has a deliverability dimension, since recipients can recognize AI-generated cadences. Personalization is therefore an outcome of architecture and live data access.
Data quality and first-party ingestion as the hidden multiplier on everything else
Even an adaptable agent can act on bad evidence. Evaluators need to separate two input problems, which are stale contact data and missing first-party context. Outdated records send outreach to the wrong people, companies, or inboxes, with deliverability damage that compounds over time. Missing account lists, deal history, and engagement signals creates a different failure. Mutiny's framework identifies how tools deprived of that specific context produce generic outputs even when the model itself is capable.
How many fields per record are verified, how recently were they re-verified, and what is the ongoing cadence? Ask whether buying intent comes from behavioral signals, including web visits, content downloads, and job-change triggers, or from static lists alone. Opt-out handling also needs to keep working after onboarding, with automatic suppression and re-verification that continues over time.
Mutiny's framework recommends asking how long after contract signature the tool can generate a recommendation using the buyer's specific account list, with answers over four weeks signaling delayed value. Development work to connect that data consumes time before the agent can perform, which makes no-code or low-code ingestion relevant. Grounding deserves equal scrutiny, because stale or irrelevant knowledge can make retrieval-augmented generation fail, producing fabricated prices, non-existent features, or incorrect delivery terms. Ask how the system prevents outputs unsupported by current, verified company data and how often its knowledge base is refreshed.
Human handoff quality as the measure of whether the AI closes the loop or opens a gap
Good inputs and capable execution reach their decisive test at handoff. An agent can research, personalize, and conduct outreach correctly, then waste much of that value by giving the human rep a meeting with missing context. The rep should not have to qualify the prospect again from zero. A useful handoff includes captured qualification answers, business pain, objections, buying urgency, and a recommended next action. It also includes the full conversation or a structured summary, with CRM fields updated and a human owner assigned.
This is where workflow ownership becomes tangible for the buyer. The tool has either completed the work through a usable transfer, or it has left the rep to assemble the pieces. The hybrid model of AI-sourced meetings handed to human closers with full context outperforms fully autonomous closing attempts on revenue generated. That makes the handoff more than an administrative convenience. It lets the rep continue a relationship.
To evaluate that transfer, ask what the rep sees at the exact moment escalation is triggered. Which information is already in the CRM record? Then ask what happens if the CRM write fails, including whether the system alerts, retries, or drops the context. Finally, ask whether reps, rather than only admins, can configure approval and escalation rules to control which handoffs require review.
Revenue attribution as the board-ready gate no vendor should be allowed to skip
A platform that passes those tests still has to earn its budget. Emails sent, calls logged, and meetings booked describe activity. Attribution can be trusted when it compares the pipeline created with a control group or matched-account baseline, since using only the prior period mixes changes in the market with the tool's impact. It also compares win rates for accounts worked with and without the tool. Cycle-time reduction needs a pre-deployment baseline captured before contract.
The measurement method must be visible during evaluation. Mutiny's framework allows customer figures to be redacted in a demo, but not the structure used to connect tool usage with outcomes. Revenue teams should record their current cost per interaction, lead response time, and handling time before signing so they have a written record to check later claims against. They should also ask for a board-ready customer case showing contribution to closed-won revenue within a defined window. Comparable deal cycles and ACV make that case relevant to the purchase.
The return calculation must include costs outside the activity dashboard. High-volume sending without deliverability governance can accumulate spam complaints and permanently damage sender domain reputation, erasing pipeline gains. Pricing needs the same close look, whether it is per seat, per outcome, or consumption-based. Unforecastable costs make the ROI case impossible to close. Even after the tool passes the technical gates, the vendor still has to show a credible contribution to revenue against those costs.
Running a structured vendor evaluation — the questions and process that apply the framework
The practical process starts before the vendor controls the screen. Document cost per interaction, lead response time, handling time, rep time spent on administration, and current win rate and cycle time by segment. Identify the system of record, whether Salesforce, HubSpot, or another CRM, and establish whether each candidate's integration is native or middleware-dependent. These choices define the test conditions. They also keep a slick demo from quietly changing the problem the team set out to test.
During demos, apply the tests in sequence rather than letting feature tours substitute for evidence. Trigger the multi-step workflow, inspect the live CRM update, then change the meeting outcome and examine the immediate recommendation. The next checks cover the time to first recommendation using the team's account list and a comparable customer's attribution methodology. The handoff record belongs in this same demonstration. One continuous account example makes the seams visible.
Mutiny's framework recommends asking what a particular seller sees at the start of a normal workday, distinguishing a managerial dashboard from specific next-best-actions for the seller. Ask where data resides and whether it trains third-party models. Establish whether pricing is forecastable at the expected usage volume.
For the pilot, Mutiny's framework recommends evaluating three to five vendors per category, since fewer tends toward overpayment and more toward decision paralysis. Use the same account brief and criteria for each candidate, follow one account from the source evidence to the next sales action, and test how the handoff works. Track activity, qualified replies, meetings, and opportunities on their own so high volume cannot hide weak conversion. At the six-month mark, check whether each rep still uses the tool.